On this page
FRM® Part I candidates should choose linear regression when the outcome is a continuous quantity, such as a loss amount, and logistic regression when the outcome is an event indicator, such as default or no default. A logistic model produces a probability after transforming a linear score, while an ordinary linear model produces an unrestricted numerical prediction. The word “regression” in both names does not make their predictions or coefficients interchangeable.
Identify the target before choosing the model
Write down exactly what the dependent variable records. If each observation has an actual amount, a continuous prediction and a residual in the same units can be meaningful. If each observation records an event as yes or no, the question is about the probability of the event and potentially a classification decision. The GARP FRM study materials place quantitative analysis within Part I; the precise distinction is well described in CFA Institute’s official linear regression and logistic regression readings. These sources support the method, while GARP remains the source for the FRM syllabus.
Suppose a risk team asks for expected credit loss in currency units. That is a numerical outcome, although a complete risk process might build it from several components. If the same team asks whether a borrower will default during a defined horizon, the observed label is binary. The horizon and event definition belong in the question before any model is fitted. “High risk” without a specified event is not a modelling target. A default indicator should also not be confused with the amount lost if default occurs; those are different variables even when they concern the same borrower.
What the straight line actually predicts
A linear regression adds an intercept and weighted predictor values. Each slope describes the expected change in the numerical outcome when its predictor increases by one unit and the other included predictors are held fixed. Ordinary least squares chooses coefficients to minimise the sum of squared residuals in the training data. That criterion penalises large errors strongly. The predicted value is expressed in the units of the original target, so a model for a loss amount gives an amount, and a model for a return gives a return.
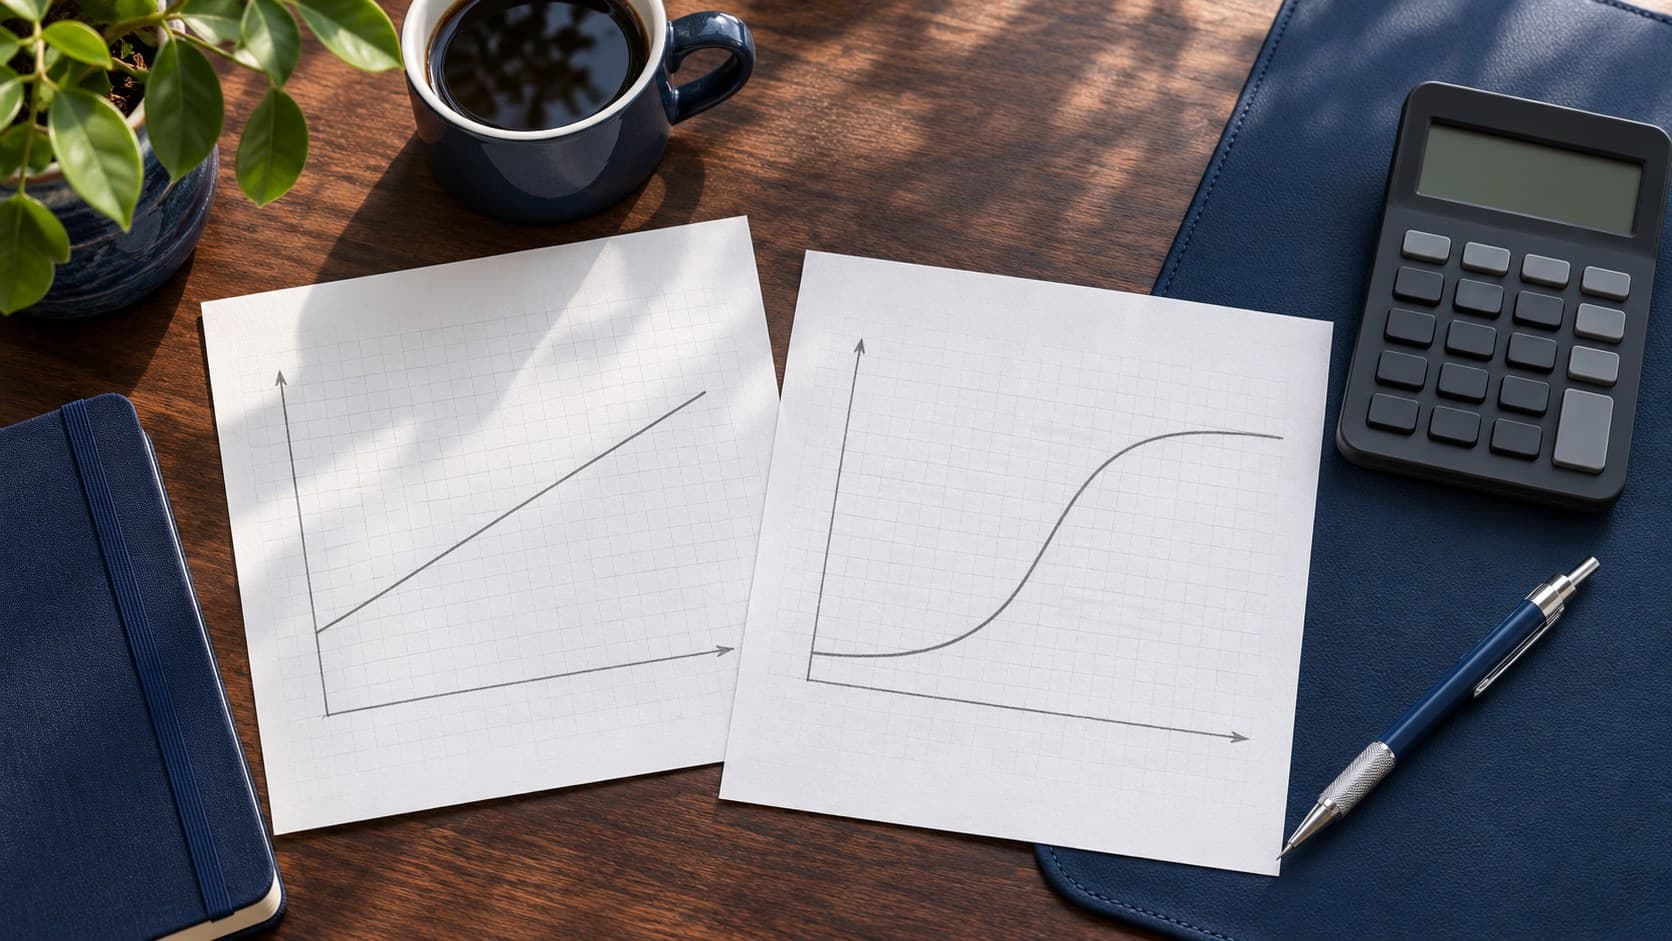
There is no built in boundary at zero or one. A fitted line can predict a negative number, or a number above one, even when historical labels happen to be zeros and ones. A negative predicted default “probability” is not a low but valid probability; it is outside the meaning of probability. A straight line fitted to a binary indicator can sometimes be used as a limited approximation in other analytical settings, but it does not solve the basic bounded probability problem the FRM candidate is being asked to recognise here. The relevant question is what the output must represent.
A linear slope is also local to its unit. If income is measured in thousands rather than single currency units, the numerical slope changes even when the relationship is the same. Before interpreting a coefficient, check the feature unit and which outcome was coded. Do not compare raw slopes across features measured on different scales as if they were a ranking of importance.
How logistic regression changes the output
Logistic regression also starts with an additive score based on an intercept and predictors. It then sends that score through the logistic function, producing a value strictly between zero and one. A score of zero corresponds to a modelled probability of one half. A larger score produces a higher probability of the event coded one, but equal changes in score do not produce equal changes in probability at every starting point. The curve flattens near the bounds. This is why the model is useful for binary events without pretending that a straight line itself is a probability.
The transformation is reversible in another useful sense: the natural logarithm of the event odds is linear in the predictors. Odds are the event probability divided by its complement. A logistic slope is the increment to logarithmic odds when its feature rises by one unit, with other inputs fixed. Exponentiating that slope gives a multiplier for the odds, not a fixed addition to the probability. CFA Institute’s extensions of multiple regression explicitly makes this coefficient distinction and describes maximum likelihood estimation for logistic models.
Because the outcome is binary, logistic estimation chooses parameters that make the observed pattern of events and non events plausible under the fitted probabilities. The usual criterion is likelihood or its logarithm, rather than ordinary least squares on the raw event labels. Numerical optimisation is typically needed. A candidate need not mistake this for a claim that the fitted probability is true for every individual; it is a model estimate conditional on the selected data and assumptions.
An invented worked example
Consider a deliberately simplified model for the event “a loan defaults within the stated horizon”. Let the logistic score be an intercept of negative two plus one times an indicator for a particular risk feature. These are invented coefficients, not data from any bank. For an applicant without that feature, the score is negative two. The logistic calculation gives roughly 0.119, or 11.9 per cent. For an applicant with the feature, the score rises by one to negative one, giving roughly 0.269, or 26.9 per cent. The difference in probability is about 15 percentage points at this starting point.
The logistic coefficient of one means that the odds multiply by the mathematical constant e, about 2.72, when the indicator changes from zero to one and other inputs stay fixed. Check the arithmetic: the first applicant’s odds are about 0.135, while the second applicant’s odds are about 0.368; their ratio is about 2.72. The coefficient does not say “one percentage point higher probability”, nor does it say the probability doubles. If the baseline probability were different, the same odds multiplier would lead to a different percentage point change. That is the distinction to retain when a vignette asks you to interpret a coefficient.
Now imagine a decision rule that flags a modelled probability above 20 per cent. The first applicant is not flagged and the second is. That rule is separate from the fitted model: changing the threshold does not change either estimated probability. If missed defaults are more costly than false alarms in a particular workflow, a lower threshold may be justified, but it also creates more false alarms. The trade off depends on the actual cost and purpose of the decision; a threshold of one half is not a universal legal or statistical requirement.
A straight line using the same score would produce negative two and negative one for those applicants, neither of which can be read as a probability. It could be meaningful if the target had been a continuous value with matching units. This contrast is intentionally simple so the method choice remains visible. The example gives no evidence about real default rates, model calibration or credit policy.
Probability, class and ranking are separate outputs
A logistic model can rank observations by fitted event probability, but a risk team may need a calibrated probability to estimate losses and a threshold to take an operational action. Good ranking does not automatically mean good calibration. A model that assigns higher scores to most eventual defaulters may still predict event frequencies that are systematically too high or too low. A candidate should therefore ask which claim is under evaluation: order, probability accuracy or classification after a cutoff.
Classifying every borrower as “no default” can look accurate when events are rare, yet miss the cases the workflow cares about. A confusion matrix separates true positives, false positives, true negatives and false negatives after a threshold is chosen. Moving the threshold changes that matrix. For a continuous forecast, error can instead be assessed by the difference between forecast and realised numerical outcome, with squared error placing extra weight on large misses. Applying a classification accuracy measure to a continuous return forecast, or a currency error measure directly to a yes or no label without a clear purpose, confuses the objects being evaluated.
Where candidates usually lose the distinction
First, they read a logistic slope as a probability change. Read it as a log odds change and translate it to an odds multiplier only when the units are clear. Second, they assume logistic regression is an ordinary straight line on zero and one labels. The additive score is linear, but the probability is transformed and bounded. Third, they treat the classification cutoff as though it were estimated with the coefficients. It is a decision rule chosen for a use case. Fourth, they assume a modelled probability is a guarantee about one borrower. Model specification, sample selection, changing conditions and calibration all affect how useful that number is.
For an efficient revision check, take a short vignette and write four items before calculating: target variable, permissible output range, coefficient interpretation and decision threshold if any. The FRM programme page helps locate quantitative analysis within the preparation path, and the learning approach can help you organise this comparison. The answer to “linear or logistic?” should follow from the target, not from which technique sounds more sophisticated.
Sources
- FRM Study Materials | GARP · garp.org · Retrieved
- Simple Linear Regression | CFA Institute · cfainstitute.org · Retrieved
- Extensions of Multiple Regression | CFA Institute · cfainstitute.org · Retrieved


